Build real apps from a prompt. Entirely on your machine.
Cascade is a local-first AI app builder powered by your own Ollama models. An agent writes the code, runs it in a sandboxed container, and shows you a live preview — no cloud, no API keys, no lock-in.
No sign-up. No telemetry. Bring your own model — ollama pull qwen3:8b and go.
cartCount / addLine. Updating each view's interface:
Ride Better.
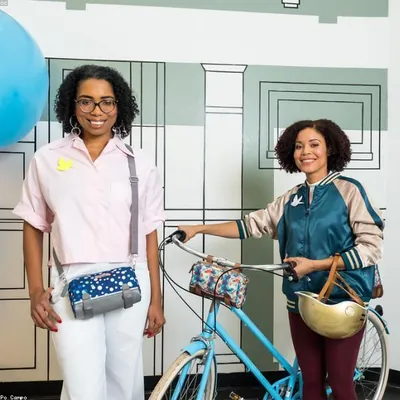 Bags & Racks3 products
 Lights & Safety2 products
 Tools & Maintenance3 products
 Accessories2 products
Bring your own key.
Cascade speaks the OpenAI wire protocol, so it points at whatever you already pay for — or at nothing at all, and stays local. Your key, your account, called directly; nothing proxies through us.
 Ollama
 OpenAI
 Groq
 OpenRouter
 NVIDIA
 vLLM
Bring your own model.
Whatever Ollama can run, Cascade can drive — swap per project, no re-install.
If Ollama runs it, Cascade runs on it qwen2.5-coderAlibaba · 1.5B–32B
 llama3.3Meta · 70B
 deepseek-r1DeepSeek · 1.5B–671B
gpt-ossOpenAI · 20B–120B
 devstralMistral · 24B
 gemma3Google · 1B–27B
qwen3Alibaba · 0.6B–235B
mistral-smallMistral · 24B
codellamaMeta · 7B–70B
Nine of the models people run most — the full Ollama library works the same way.
Prompts, code and data never leave the machine.
Nothing to sign up for. Add your own key later only if you want cloud.
Every line public — read it, fork it, ship with it.
Swap models per project — 7B laptop to 70B workstation.
Tune every model.
Down to the token.
Cascade ships a full model manager — curate your picker, set the context window and output cap per model, dial sampling, and manage provider keys. Changes apply live, on the next turn.
Curate what shows in the picker — add by name or straight from a provider's catalog, then switch in one click.
Context window, max output tokens, temperature and top-p — per model, with Auto to defer to the backend default.
Ollama runs local; OpenAI, Groq, OpenRouter and NVIDIA take your key. Set it for the session or persist it in .env.
No restart, no re-index. Save and the very next turn uses the new model and settings.
Curate the models in your picker, add models manually or from a provider's catalog, and tune each model's context window, output cap, and sampling. Changes apply live — no restart.
Every turn, on the record.
Nothing extra to run.
Local models fail in ways you have to see to fix — a loop that never converges, a cache miss that doubles every call, a plan the model quietly ignored. Cascade ships its own trace viewer, writing to a file on your disk. No collector, no Python service, no account.
One message is one trace — every model call, every tool call and every sub-agent it delegated to, in the order they happened.
Not a preview. The entire message list as sent, the reasoning kept as reasoning, every tool's input and output — stored uncapped.
Tokens per call and real context occupancy. On local backends prefill and decode split out — a cold cache reads nothing like a slow model.
Every failed command, every turn that touched a file, every loop breaker that fired — across your whole history, not one trace at a time.
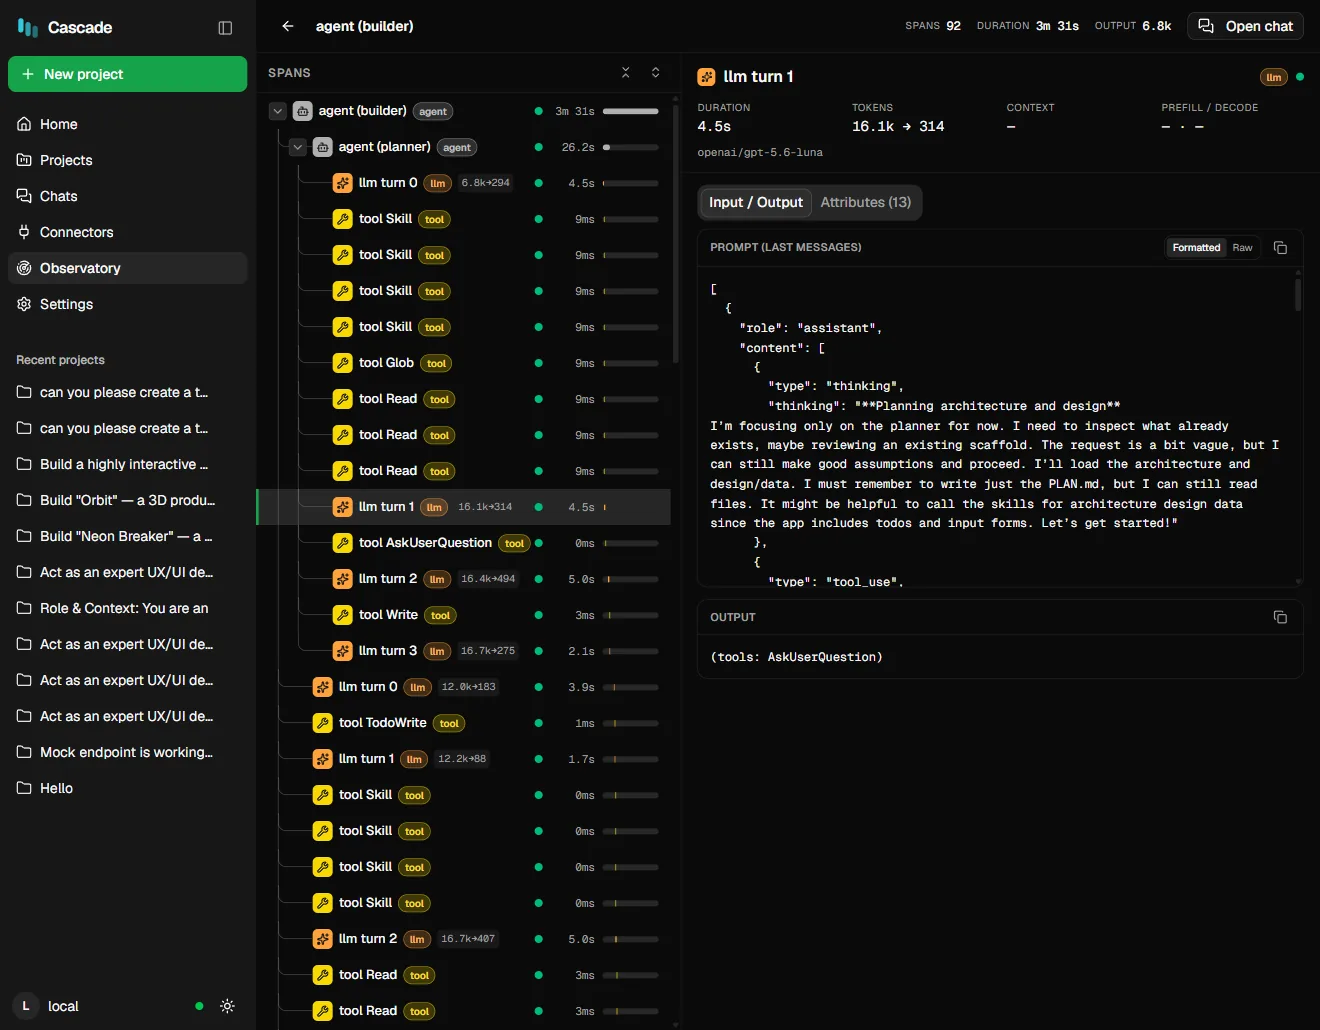
Already have Phoenix, Langfuse or another OTLP collector? Point Cascade at it with one environment variable — the same traces, exported as OpenTelemetry spans, with nothing to change.
Everything the cloud builders do.
Nothing they take from you.
The full prompt-to-running-app loop — chat, code, sandbox, preview — rebuilt from first principles to run on your hardware, with your models.
Yours, entirely
Your prompts, your code, your data — none of it leaves your machine. No accounts, no telemetry, no usage caps. Work on a plane, in a lab, or behind an air gap.
Sandboxed by design
Every project gets its own Docker container. The agent's shell commands and dev server run inside it — it can build anything without ever touching your machine.
Live preview, instantly
The dev server runs in the sandbox and streams straight into the builder. Prompt, watch the diff, see it running — one loop, no deploys.
A real agent engine
Not a prompt wrapper — a full agentic loop with tools, permissions, subagents, 3-tier memory, context compaction and error recovery.
Watch it think
An activity-first timeline shows every file written, every command run, live — and the answer streams in right beside it.
One engine, everywhere you work
The same headless core drives every frontend over one protocol — use the app builder in your browser, the agent inside VS Code, or the desktop app for Windows, macOS and Linux.
Prompt to running app in three steps.
Describe what you want
Start from a template and tell the agent what to build — a store, a dashboard, a game. Plain words, no boilerplate.
The agent builds it
It plans, writes files, installs dependencies and fixes its own errors — every step visible in the live activity timeline.
See it run. Keep going.
The dev server spins up in the project's container and appears in the preview pane. Iterate by chatting — every change is git-tracked.
Questions about Cascade, answered.
What is Cascade?
Cascade is a free, open-source AI app builder that runs on your own computer. You describe the app you want in plain words; an AI coding agent writes the code, runs it in a sandboxed container and shows you a live preview.
Is Cascade free?
Yes. Cascade is open source under the MIT license. There is no paid tier, no seat license and no account to create.
Does it work with local models and without the cloud?
Yes — that is what it is built for. Cascade runs on your own Ollama models, so your prompts, code and data stay on your machine. You only need the internet to download models and npm packages.
Which AI models can I use?
Any model that supports tool calling. Locally that means the Ollama library — Qwen 3, Llama 3.3, gpt-oss, DeepSeek R1, Gemma 3, Devstral and more. You can also bring your own key for OpenAI, Groq, OpenRouter or NVIDIA, or point Cascade at any OpenAI-compatible server such as vLLM or LM Studio.
Do I need a GPU?
You need whatever your chosen model needs. Smaller models run on ordinary laptops; larger ones need more memory but build more complete apps. A context window of 32k works, and 64k or more is better for whole-app builds.
What can I build with it?
Web apps: online stores, landing pages, dashboards, games and more. Each one is a real React, Vite and Tailwind project in a folder on your disk, with a version saved for every change, so the code is yours to keep.
How do I get started?
Download the desktop app for Windows, macOS (Apple Silicon) or Linux and open it. It ships its own Node.js and toolchains, so there is nothing else to install first: add your Ollama models or an API key and describe the app you want. You can also run it from source — the README on GitHub has the commands.